Technology
Generative Synchronous Diffusion
The fourth pillar of generative AI. Every layer of a video, in one pass.
Four Pillars
Four Pillars. GSD Is the Fourth.
Each one changed what AI could make. GSD changes the complexity class.
Pillar One · Language
Attention
Θ(N²)per layer
Gave us language models.
Pillar Two · Clips
Diffusion Transformer
Θ(L·M²·N²)
Gave us today’s video models.
Pillar Three · Streams
State Space Model
O(N)
Gave us long streams.
Pillar Four · Wishtales GSD
Topological Graph World Model
O(M log N + N)
The whole video, every layer, in one pass.
M: synchronised modalities. N: sequence length. L: denoising steps.
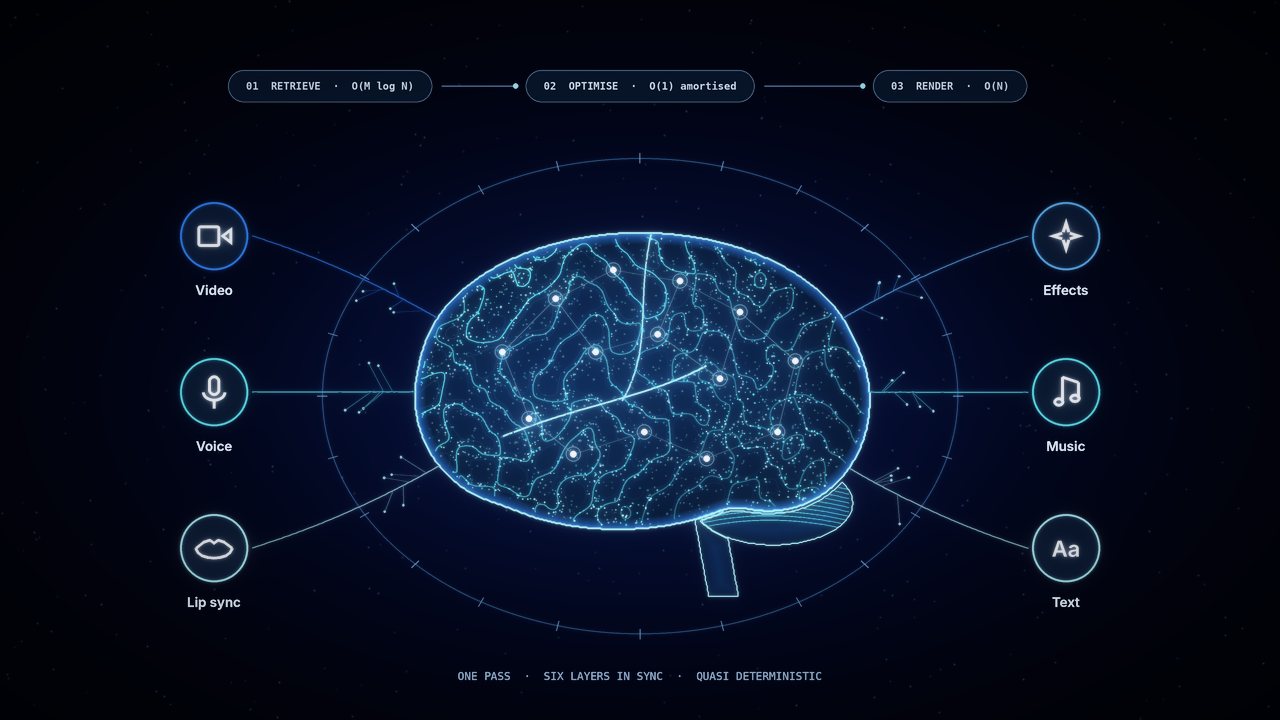
How GSD Works
Plan Once. Render Once.
GSD understands the whole story first, then executes it.
- Video
- Voice
- Lip sync
- Effects
- Music
- Text
Symbolic Layer
Retrieve
O(M log N)Finds every character, voice and sound the story needs in the world graph.
Combinatorial Optimisation
Optimise
O(1) amortisedLocks one quasi-deterministic blueprint. Every sync decision, made once.
Neural Layer
Render
O(N)Six layers from one shared state, in a single linear pass.
“Synchronisation is a property of the architecture, not a correction applied to the output.”
120 s+
One shot, 154 s demonstrated
≈240 s
To render 120 seconds of six-layer 4K video
≈67×
Realised inference efficiency
Zero
Denoising steps
Measured on NVIDIA Blackwell B300.
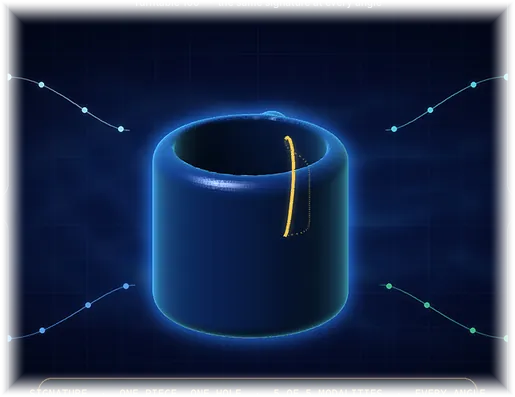
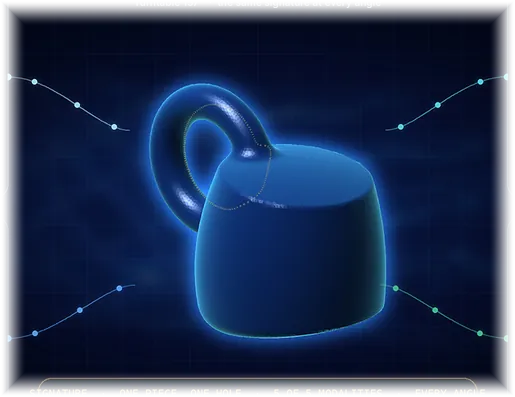
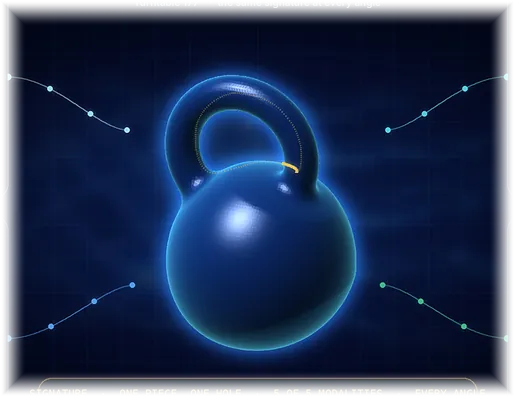
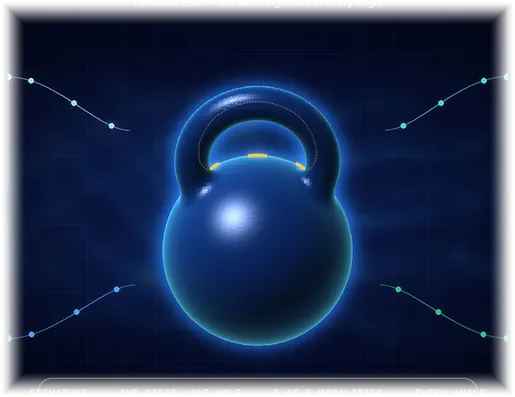
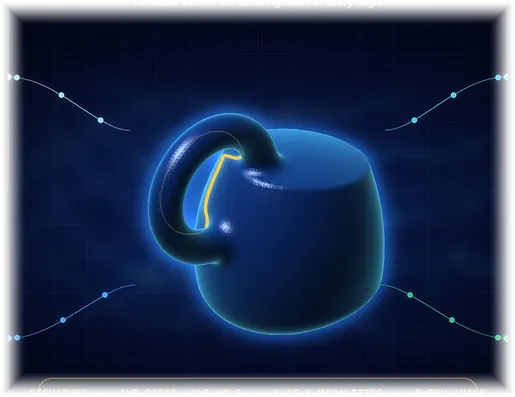
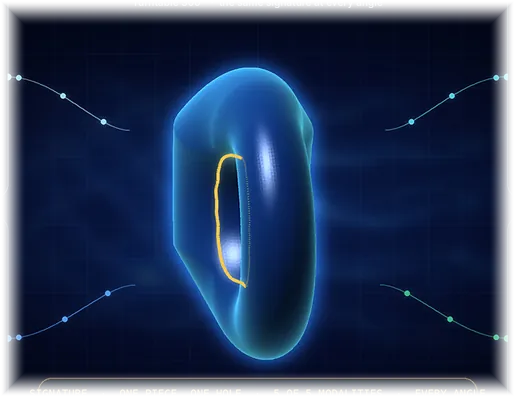
Topological Identity
Where Shape Replaces Text Embeddings.
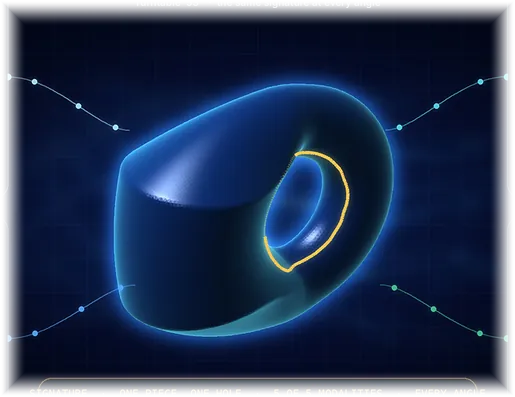
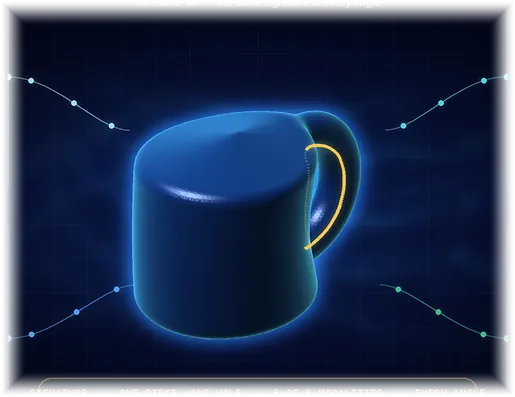
One Topological Graph Signature holds identity across every modality, every scene and every edit.
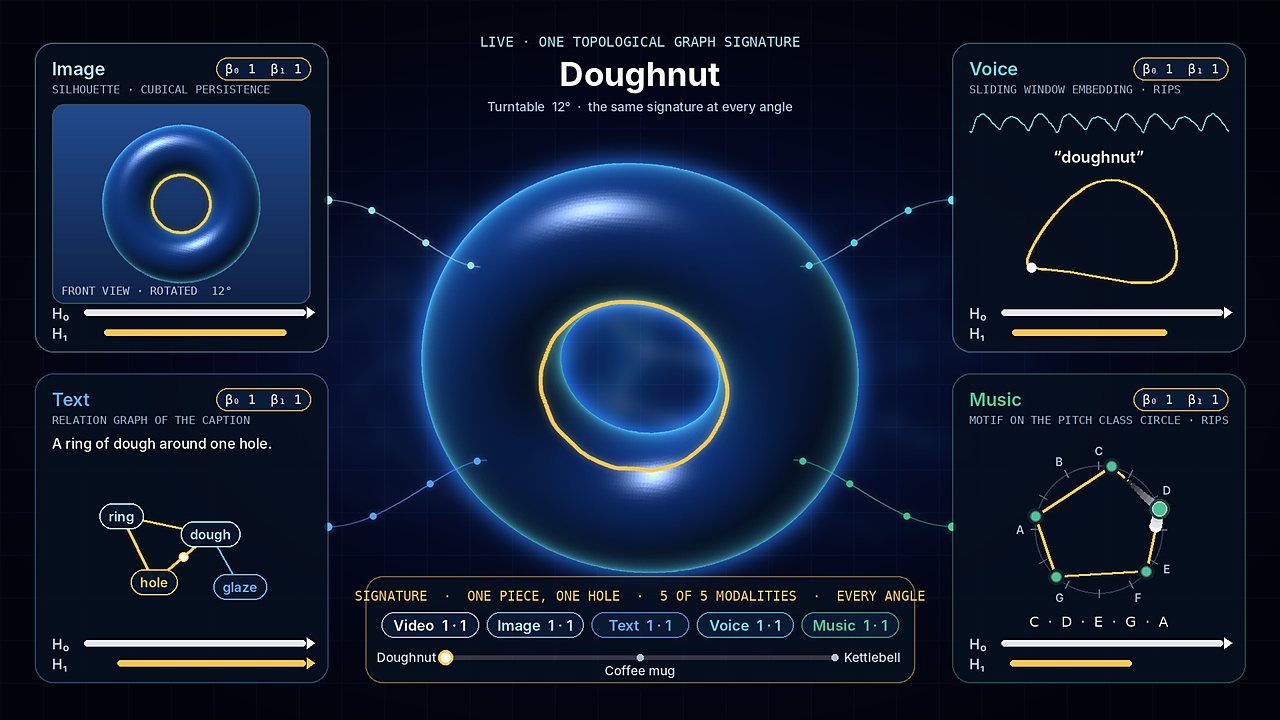
98.99%
Prompt to physics adherence
99.89%
Prompt constraint adherence
Across 10,000 outputs, measured on NVIDIA Blackwell B300.
Giga Papaya
Editing to the Second.
Only the chosen layer re-renders for the chosen seconds.
Benchmarks
Five Numbers That Define the Gap.
Version 2026 evaluation against the commercial frontier.
29 of 39
Benchmark categories led
| Measure | Wishtales GSD | Leading video models | Gap |
|---|---|---|---|
| Single pass, no cuts | 120 s+, 154 s demonstrated | 8 to 30 s | 4× or more |
| Native quality | 4K at 50 fps, whole pass | 720p to 4K, 24 to 60 fps, for 8 to 30 s | Same fidelity, many times the length |
| Speed, output s per wall-clock s | 0.5, six layers | 0.03 to 0.09, one layer | 5× to 17× |
| Price per minute with audio | USD 2, six layers, ten edits | USD 24 to 42 | 12× to 21× |
| Editable layers | 6, to one second | 2: video and one mixed track | Different in kind |
Wishtales measured on NVIDIA Blackwell B300 at FP8. Leading video models: Seedance, Veo, Kling, Runway and Sora, from public documentation, hosted medians and list pricing for premium tiers with native audio.
Responsible by Design
Safety, Governance and Ethics, Built In.
The rules live inside the world graph, not in a filter after the fact.
Safe by Construction
Harmful concepts are left out of the world graph, so they cannot be generated.
Governed for Enterprise
Brand rules and prohibited concepts are enforced inside the graph, as the video is made.
Ethical by Default
No deepfakes. What is left out of the world graph cannot be made, so misuse stops before a single frame exists.
Traceable
Every creative decision is reproducible and reversible, from one quasi-deterministic blueprint.